 aionedge.
Jev project · Benchmarks & research
jev-for-engineers
Foadsf/jev-for-engineers
Eight mechanical and electrical engineering experiments using Jev for task routing, log checks and component selection.
- GitHub stars
- 3 as of 2026-09-22
- Forks
- 0
- Language
- Python
- License
- MIT
- Created
- 2026-09-16
- Last updated on GitHub
- 2026-09-16
- Added to AionEdge
- 2026-09-19

Built by this developer
Foad S. FarimaniWhat Jev does in jev-for-engineers
Jev classifies engineering text and candidates; calculations and final actions stay in Python rules.
Verification
Verified. We confirmed this repository through the GitHub API and located the code that calls Jev at a pinned commit: view the Jev code ↗. Upstream code changes over time, so check that the file still exists at the current commit before citing it.
Topics
- cad
- cae
- calibrated-confidence
- classification
- jev
- llm
- mechanical-engineering
- typesafe
How Benchmarks & research projects use Jev
Benchmarks and research projects test Jev rather than just use it. They compare it with language models and other classifiers, check whether its probabilities are well calibrated, and explore where the decision-model approach breaks down.
Also listed in: Routing & Cost Optimization.
Related Jev projects in Benchmarks & research
- jev-behavior-studyRINNECODER/jev-behavior-studyAn independent Jev 1.13.0 behavior study recording successes and failures across question framing, input conditions and games.★ 3
Python - jev-explorationSamuelSacco/jev-explorationA research repository tracking Jev claims and limitations, with calibration experiments and runnable examples.★ 3
Python - jev-does-not-play-diceKantaHayashiAI/jev-does-not-play-diceExperiments on Jev’s probability calibration, uncertainty reporting, and forecast probability preservation.★ 4
JavaScript 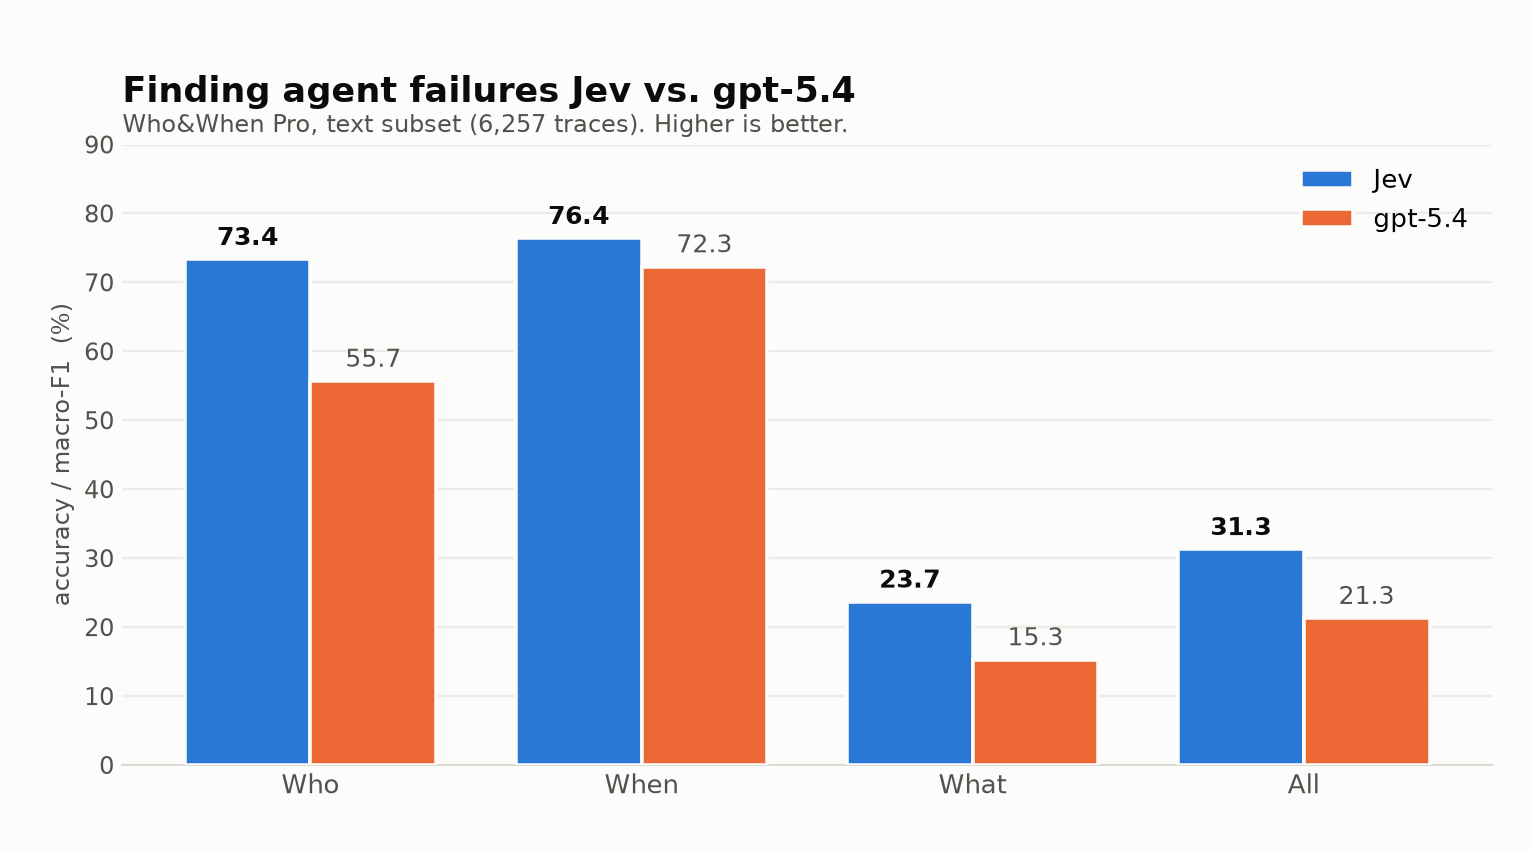 jev-agent-failure-benchmarkTokenTrim/jev-agent-failure-benchmarkA benchmark using Jev to attribute multi-Agent failures to an Agent, step and error type.★ 2
Python- jev-medhallu-benchmarkstperic/jev-medhallu-benchmarkTypeSafe's Jev and four fast LLMs added to Stanford MedHELM's MedHallu results: harness, preregistered run plans and every run file.★ 2
Python - decision-benchHanno-Labs/decision-benchOpen benchmark runtime for document-grounded decision models.★ 1
Python