 aionedge.
jev-dspy-lab
Reproducible calibration and selective-risk benchmarks for Jev/TypeSafe decisions in DSPy workflows
- GitHub stars
- 3 as of 2026-09-22
- Forks
- 0
- Language
- Python
- License
- MIT
- Created
- 2026-09-17
- Last updated on GitHub
- 2026-09-20
- Added to AionEdge
- 2026-09-22

What Jev does in jev-dspy-lab
The project describes itself this way: Reproducible calibration and selective-risk benchmarks for Jev/TypeSafe decisions in DSPy workflows In the Benchmarks & research category, Jev typically decides labels and probabilities on fixed test sets, so accuracy, calibration and latency can be measured.
Verification
Verified. We confirmed this repository and its Jev relevance through the GitHub API and the source lists below. A specific file link has not been recorded yet.
How Benchmarks & research projects use Jev
Benchmarks and research projects test Jev rather than just use it. They compare it with language models and other classifiers, check whether its probabilities are well calibrated, and explore where the decision-model approach breaks down.
Related Jev projects in Benchmarks & research
- jev-for-engineersFoadsf/jev-for-engineersEight mechanical and electrical engineering experiments using Jev for task routing, log checks and component selection.★ 3
Python - jev-behavior-studyRINNECODER/jev-behavior-studyAn independent Jev 1.13.0 behavior study recording successes and failures across question framing, input conditions and games.★ 3
Python - jev-explorationSamuelSacco/jev-explorationA research repository tracking Jev claims and limitations, with calibration experiments and runnable examples.★ 3
Python - jev-does-not-play-diceKantaHayashiAI/jev-does-not-play-diceExperiments on Jev’s probability calibration, uncertainty reporting, and forecast probability preservation.★ 4
JavaScript 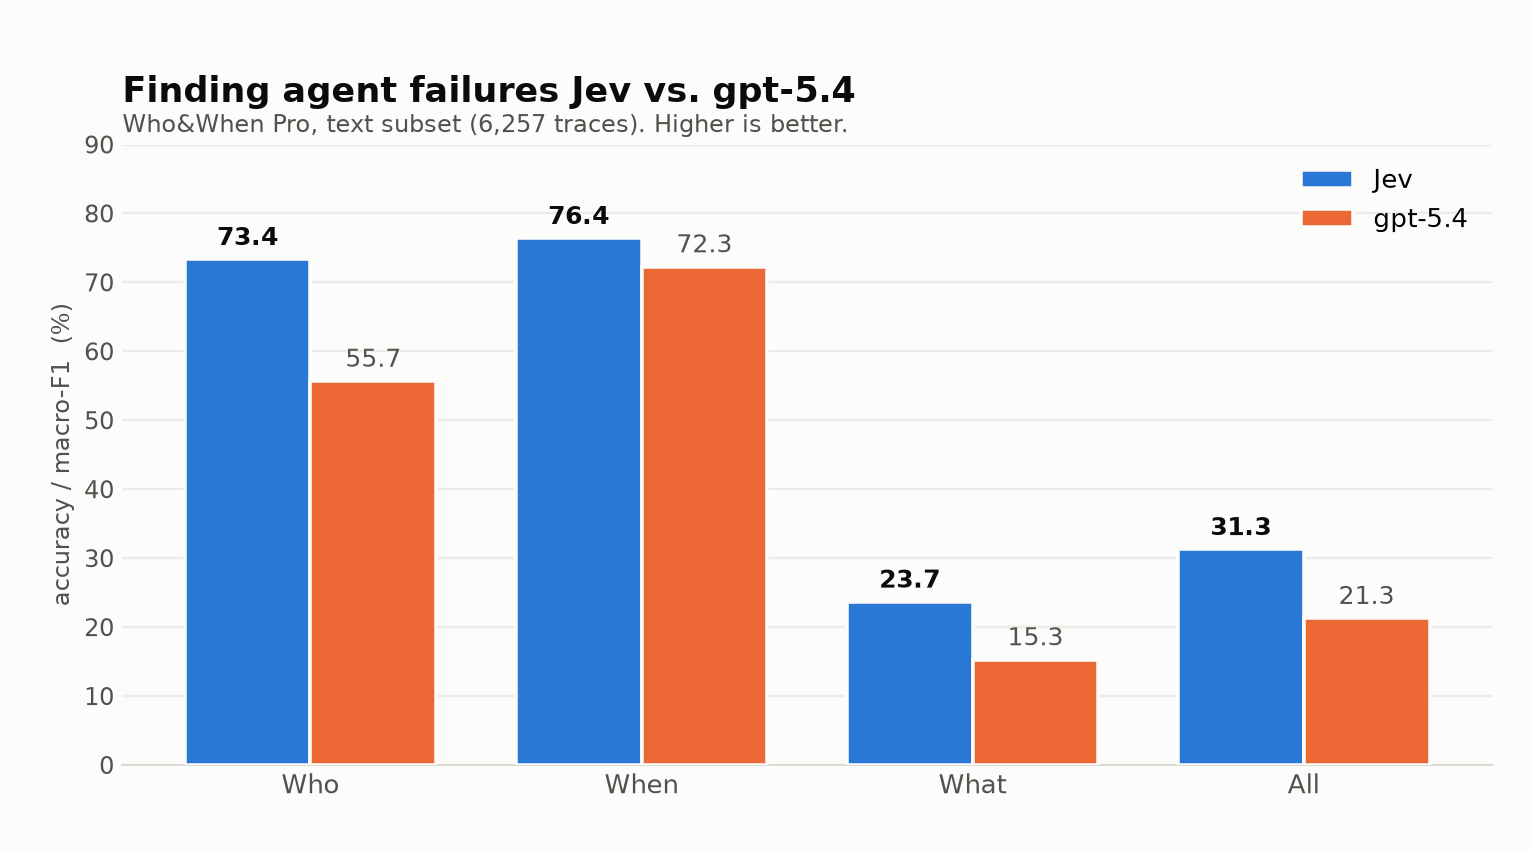 jev-agent-failure-benchmarkTokenTrim/jev-agent-failure-benchmarkA benchmark using Jev to attribute multi-Agent failures to an Agent, step and error type.★ 2
Python- jev-medhallu-benchmarkstperic/jev-medhallu-benchmarkTypeSafe's Jev and four fast LLMs added to Stanford MedHELM's MedHallu results: harness, preregistered run plans and every run file.★ 2
Python