 aionedge.
jev-vs-clef
Launch-window comparison harness for Jev and Cloudflare Clef decision models on synthetic decision tasks.
- GitHub stars
- 0 as of 2026-10-05
- Forks
- 0
- Language
- Python
- License
- Check upstream
- Created
- 2026-10-03
- Last updated on GitHub
- 2026-10-04
- Added to AionEdge
- 2026-10-05

What Jev does in jev-vs-clef
Measures agreement, latency and bounded-task accuracy using recorded calls. The small synthetic workload is not a production safety or general-quality guarantee. Catalog verification inspected README and source; the application was not independently runtime-tested.
Verification
Verified. We confirmed this repository through the GitHub API and located the code that calls Jev at a pinned commit: view the Jev code ↗. Upstream code changes over time, so check that the file still exists at the current commit before citing it.
Topics
- benchmark
- clef
- decision-models
- jev
- llm-evaluation
How Benchmarks & research projects use Jev
Benchmarks and research projects test Jev rather than just use it. They compare it with language models and other classifiers, check whether its probabilities are well calibrated, and explore where the decision-model approach breaks down.
Related Jev projects in Benchmarks & research
- jev-calibration-auditjujumilk3/jev-calibration-auditAudits Jev calibration, option-wording effects and Korean judgments through public APIs and datasets.★ 0
Python - jev-transcript-screenerkeduseworku/jev-transcript-screenerDemo and evaluation harness that uses Jev to rank solver transcripts for review by a more costly judge.★ 0
Python - jev-comparewestsmith-open/jev-compareSide-by-side Jev and Gemini evaluation harness comparing typed decisions, requests, latency, cost and calibration.★ 0
HTML - decision-benchHanno-Labs/decision-benchOpen benchmark runtime for document-grounded decision models.★ 1
Python - jev-synergy-screeningPistachioAIHQ/jev-synergy-screeningA Jev title-and-abstract screening experiment compared with Cohen Abstract Triage labels for an ADHD review.★ 1
Python 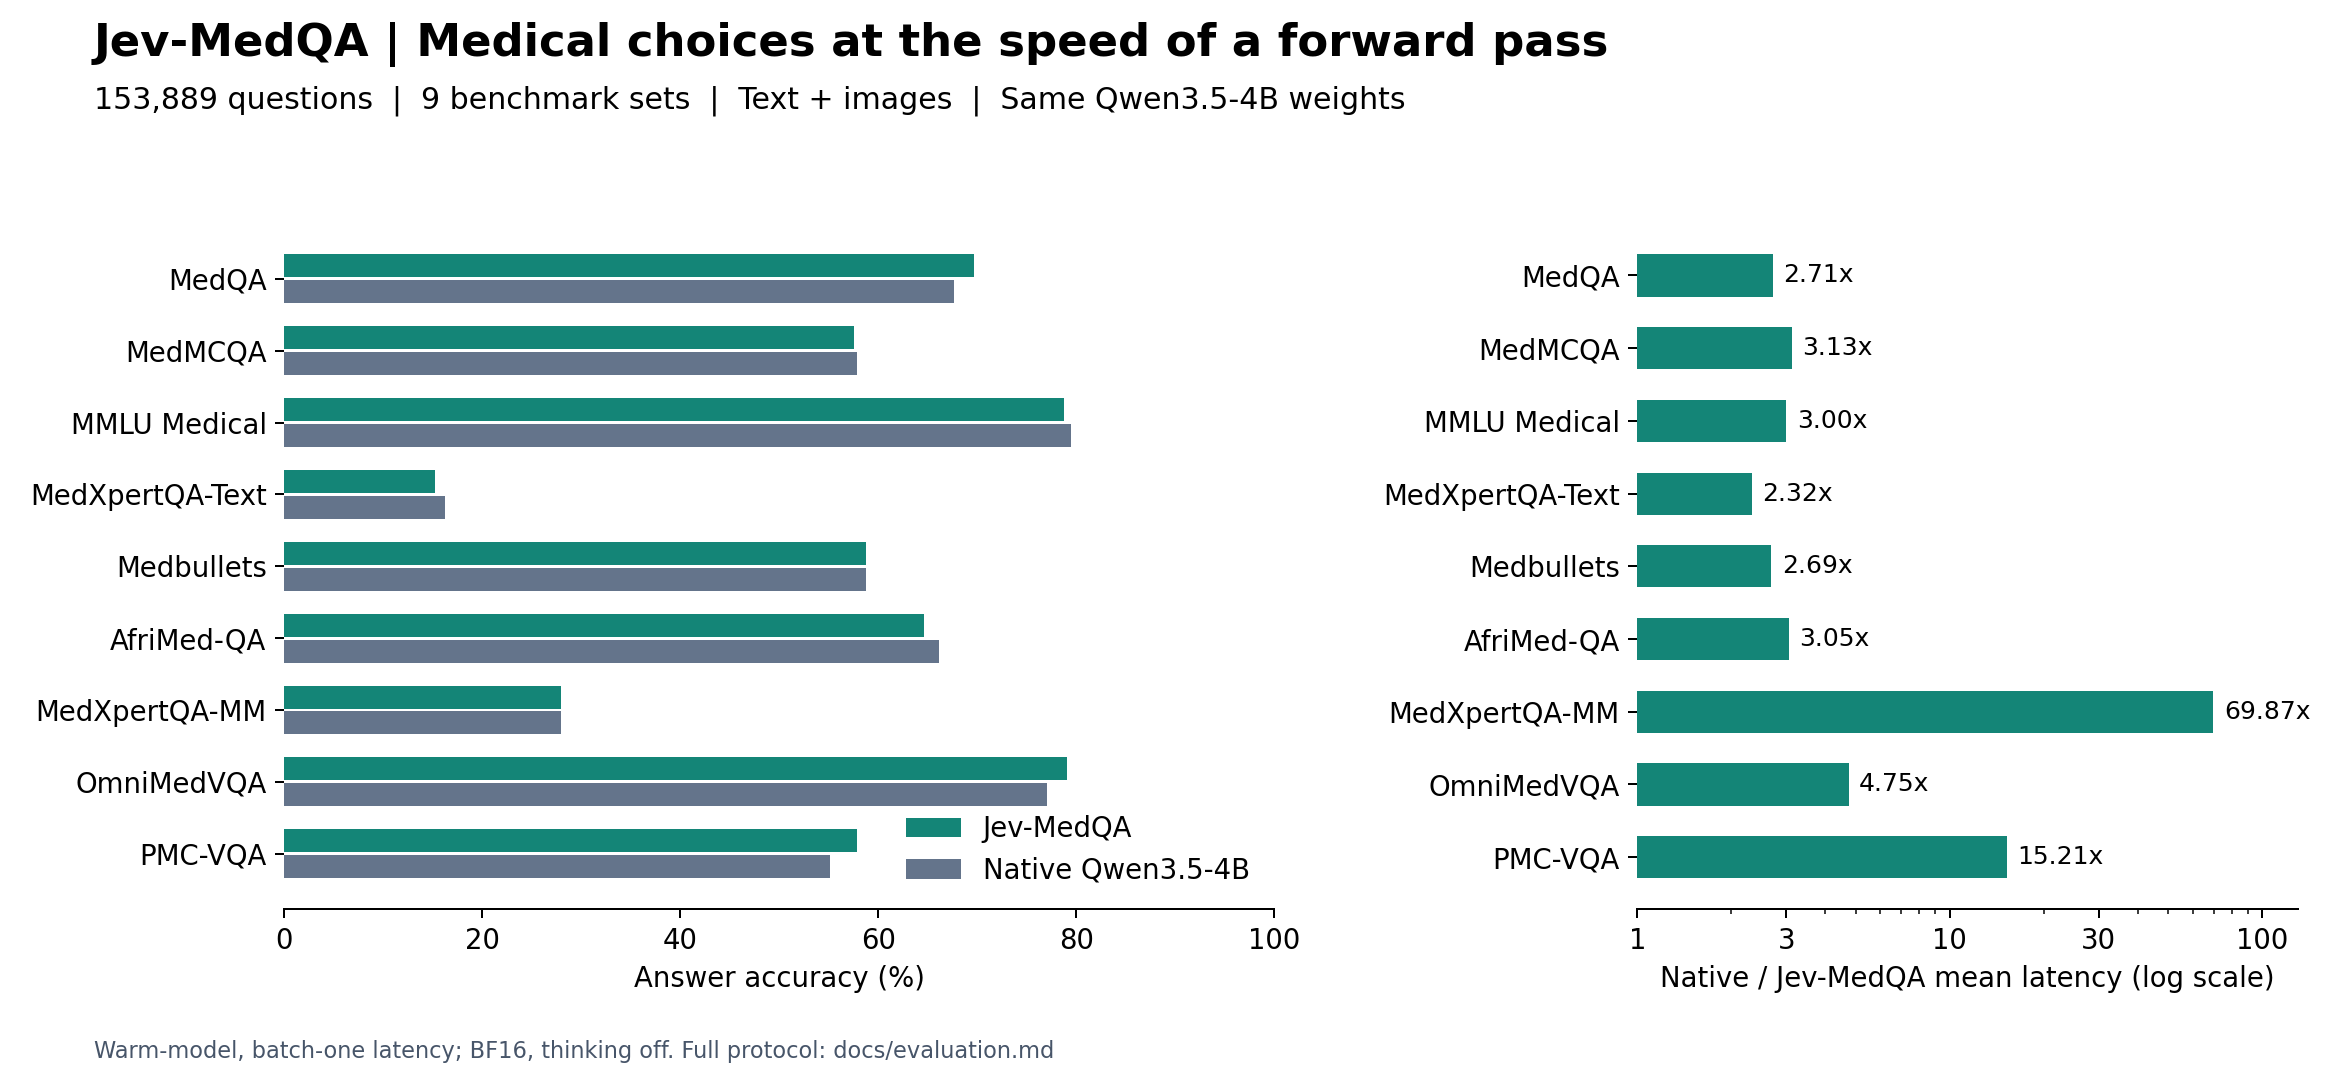 Jev-MedQAZtrura/Jev-MedQAExperiments running Jev on medical multiple-choice question answering.★ 1
Python