 aionedge.
jev-on-a-laptop
Unofficial study: Jev-style parallel typed decisions on stock 1.5B-8B models on an Apple Silicon laptop. Benchmarks, research notes, and a Hugging Face Space demo.
- GitHub stars
- 23 as of 2026-09-22
- Forks
- 1
- Language
- Python
- License
- Check upstream
- Created
- 2026-09-16
- Last updated on GitHub
- 2026-09-17
- Added to AionEdge
- 2026-09-19

What Jev does in jev-on-a-laptop
The project describes itself this way: Unofficial study: Jev-style parallel typed decisions on stock 1.5B-8B models on an Apple Silicon laptop. Benchmarks, research notes, and a Hugging Face Space demo. In the Benchmarks & research category, Jev typically decides labels and probabilities on fixed test sets, so accuracy, calibration and latency can be measured.
Verification
Verified. We confirmed this repository and its Jev relevance through the GitHub API and the source lists below. A specific file link has not been recorded yet.
How Benchmarks & research projects use Jev
Benchmarks and research projects test Jev rather than just use it. They compare it with language models and other classifiers, check whether its probabilities are well calibrated, and explore where the decision-model approach breaks down.
Related Jev projects in Benchmarks & research
- jevifyaltryne/jevifyAn Agent Skill for finding suitable Jev decision points and designing questions and comparison experiments.★ 24
Python - jev-curateAkashPriyadarshii/jev-curateA Rust dataset-filtering experiment using Jev scores to keep or reject text records.★ 26
Rust - jev-benchmarksAbdelStark/jev-benchmarksA benchmark comparing Jev and GLiNER on text classification, probability calibration and selective automation.★ 17
Python 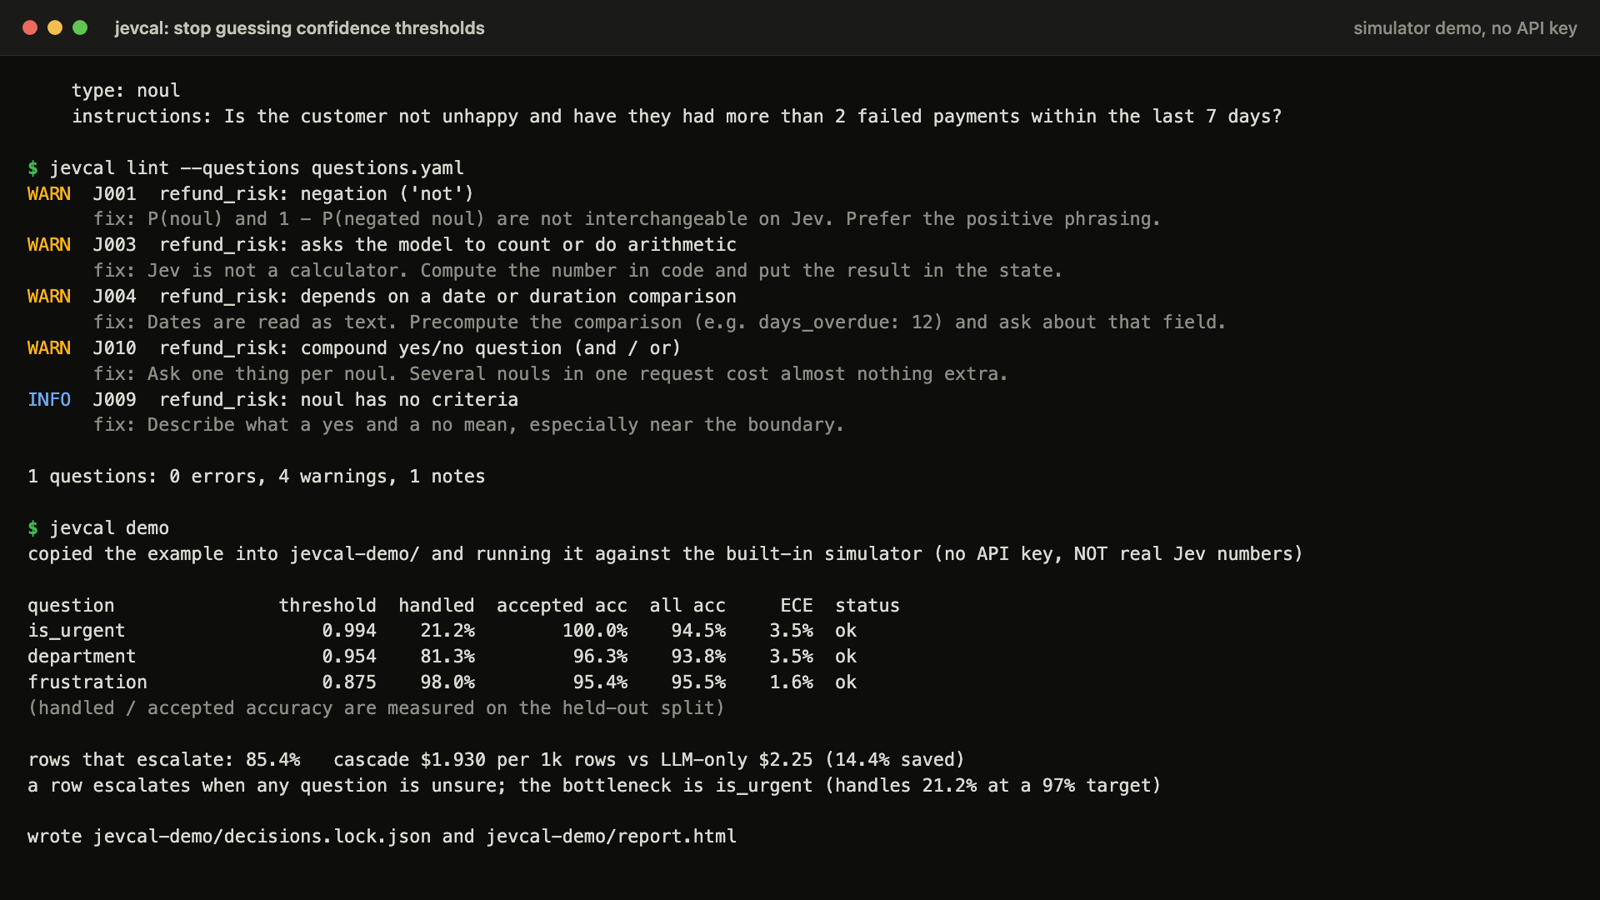 jevcalabhixhek/jevcalA toolkit for evaluating Jev probabilities on labeled data, selecting confidence thresholds and checking model drift.★ 10
Python- typesafe-ai-benchmarkiammrduncan/typesafe-ai-benchmarkCompares Jev with other structured-output models on shared application tasks, recording errors, latency, Tokens, and estimated cost.★ 38
TypeScript - jev-lmy0usaf/jev-lmA word-level generation experiment that asks Jev to select words or verify locally drafted continuations.★ 6
TypeScript