 aionedge.
openjev-experiments
Experiments with openjev, an open Jev-style option-logit runner, on local models.
- GitHub stars
- 1 as of 2026-09-22
- Forks
- 0
- Language
- Python
- License
- MIT
- Created
- 2026-09-17
- Last updated on GitHub
- 2026-09-17
- Added to AionEdge
- 2026-09-19

What Jev does in openjev-experiments
The project describes itself this way: Experiments with openjev, an open Jev-style option-logit runner, on local models. In the Benchmarks & research category, Jev typically decides labels and probabilities on fixed test sets, so accuracy, calibration and latency can be measured.
Verification
Verified. We confirmed this repository and its Jev relevance through the GitHub API and the source lists below. A specific file link has not been recorded yet.
Topics
- jev
- openjev
How Benchmarks & research projects use Jev
Benchmarks and research projects test Jev rather than just use it. They compare it with language models and other classifiers, check whether its probabilities are well calibrated, and explore where the decision-model approach breaks down.
Related Jev projects in Benchmarks & research
- decision-benchHanno-Labs/decision-benchOpen benchmark runtime for document-grounded decision models.★ 1
Python - jev-synergy-screeningPistachioAIHQ/jev-synergy-screeningA Jev title-and-abstract screening experiment compared with Cohen Abstract Triage labels for an ADHD review.★ 1
Python 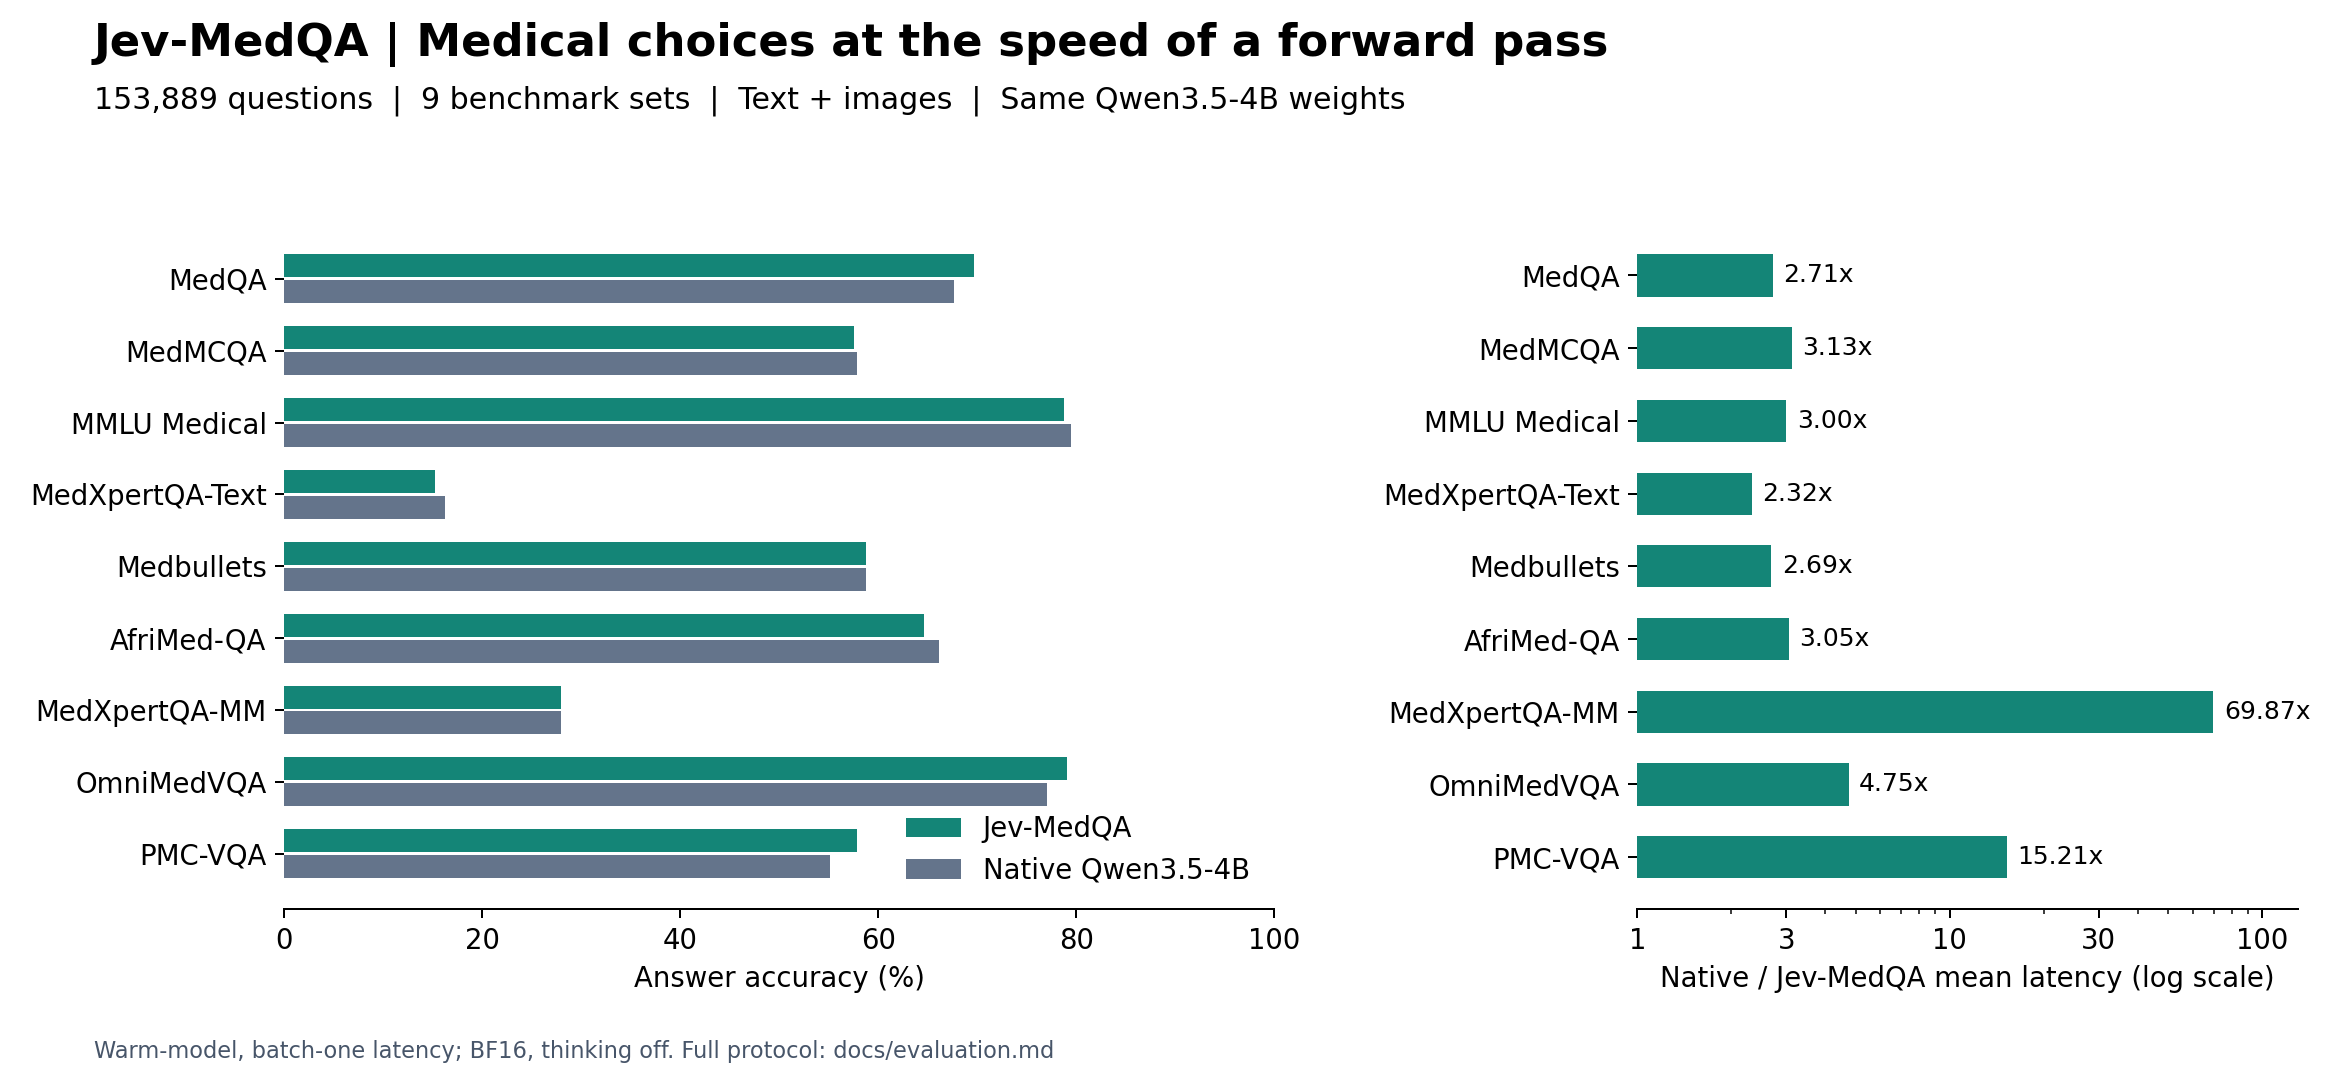 Jev-MedQAZtrura/Jev-MedQAExperiments running Jev on medical multiple-choice question answering.★ 1
Python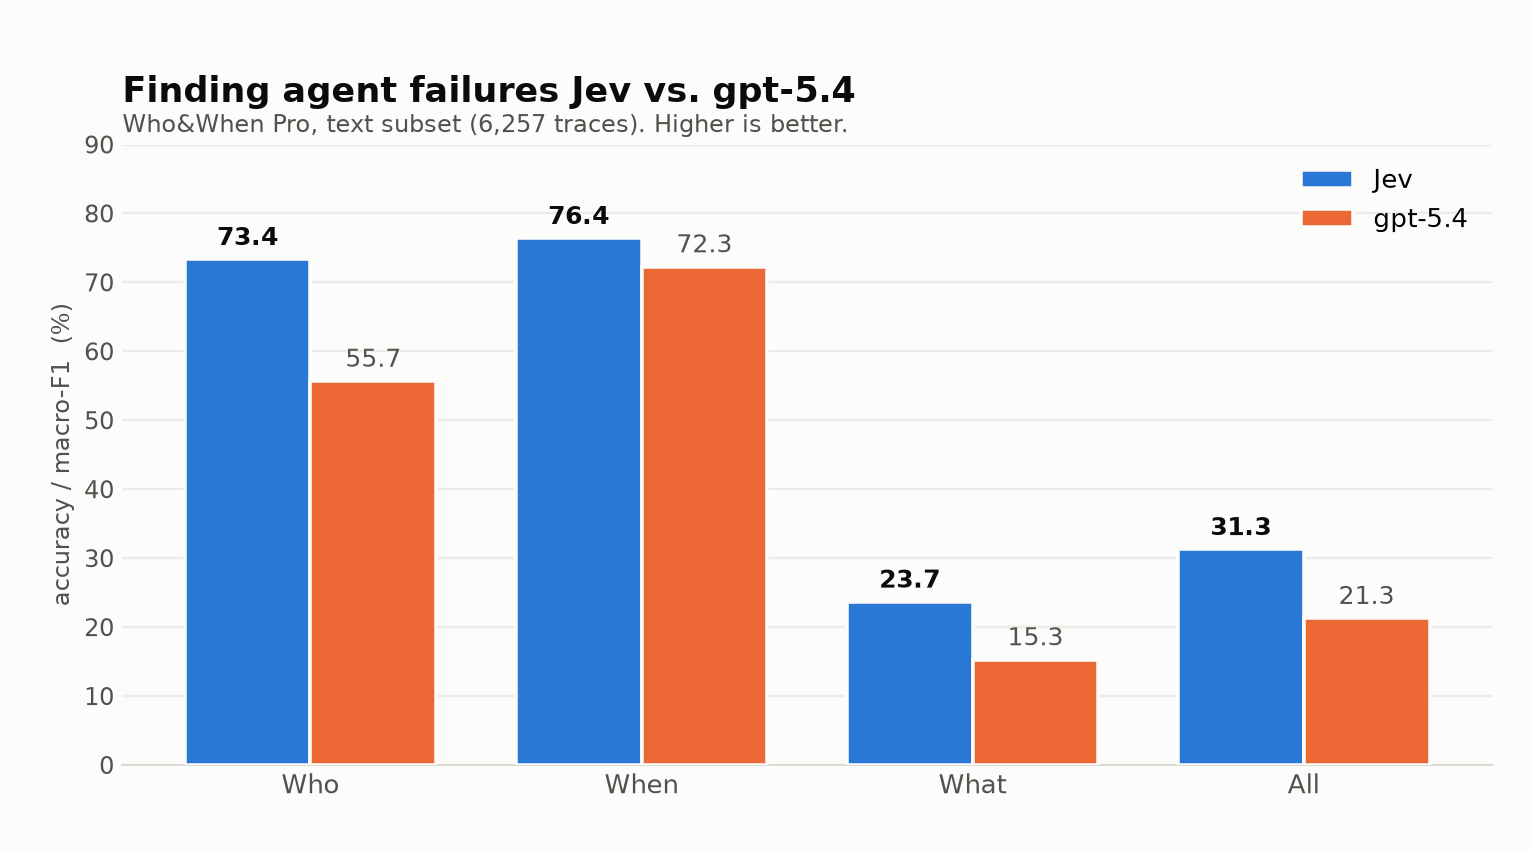 jev-agent-failure-benchmarkTokenTrim/jev-agent-failure-benchmarkA benchmark using Jev to attribute multi-Agent failures to an Agent, step and error type.★ 2
Python- jev-calibration-auditjujumilk3/jev-calibration-auditAudits Jev calibration, option-wording effects and Korean judgments through public APIs and datasets.★ 0
Python - jev-transcript-screenerkeduseworku/jev-transcript-screenerDemo and evaluation harness that uses Jev to rank solver transcripts for review by a more costly judge.★ 0
Python